variational autoencoders
- there are some challenges with normal autoencoders:
- the latent space is unorganized
- sampling randomly from the latent space generates no meaningful reconstruction
- even sampling close to the actual representation does not generate meaningful reconstruction
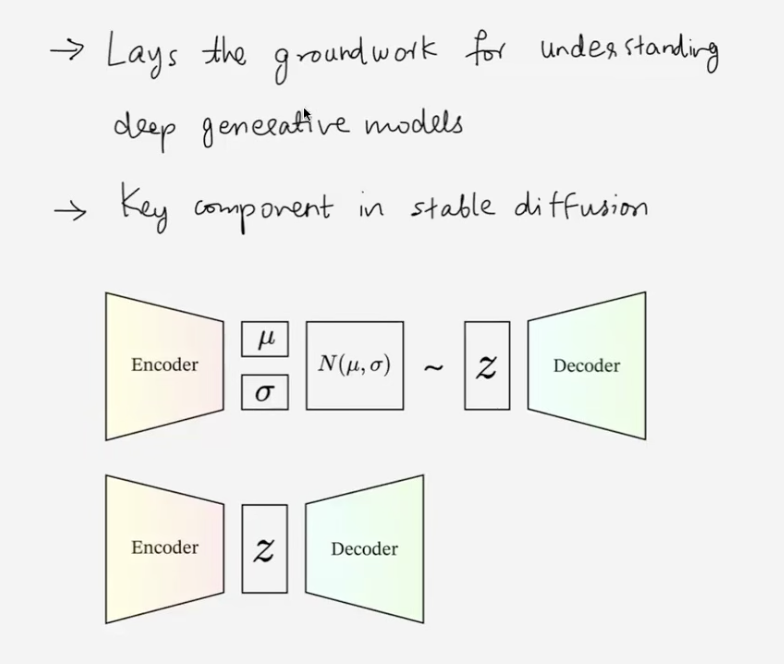
paper - https://arxiv.org/abs/1312.6114
-
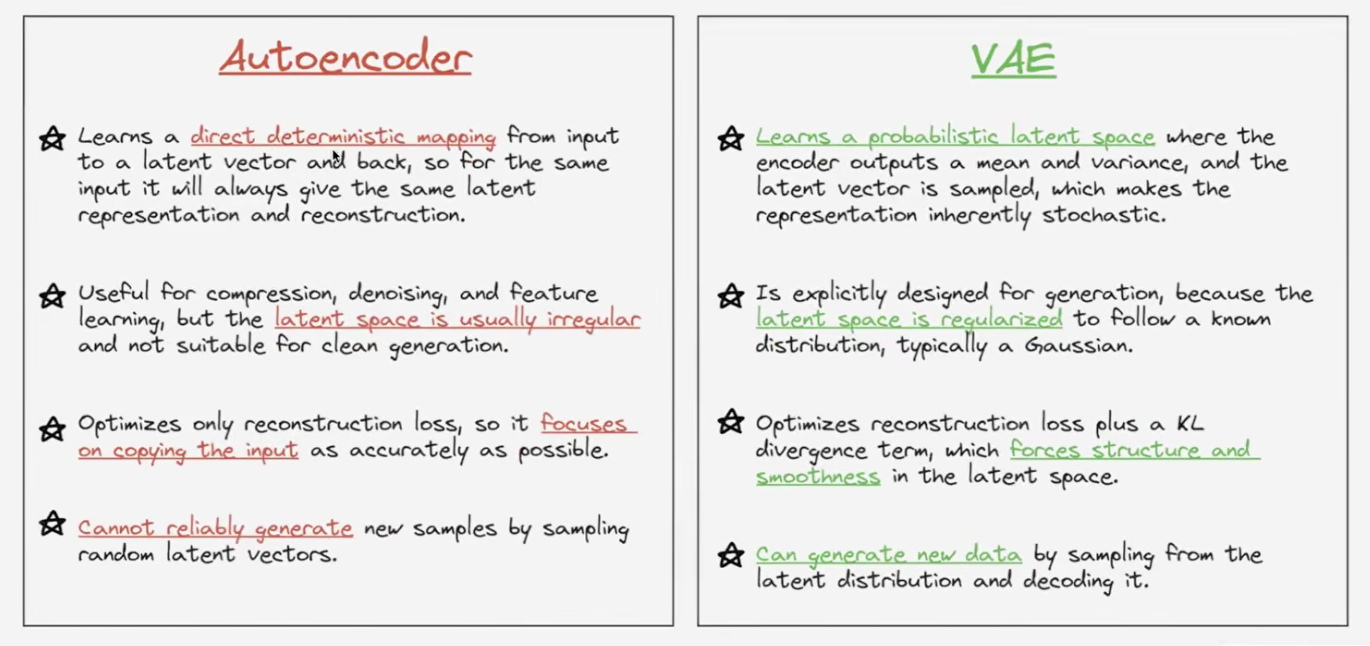
autoencoder vs VAE
-
autoencoder
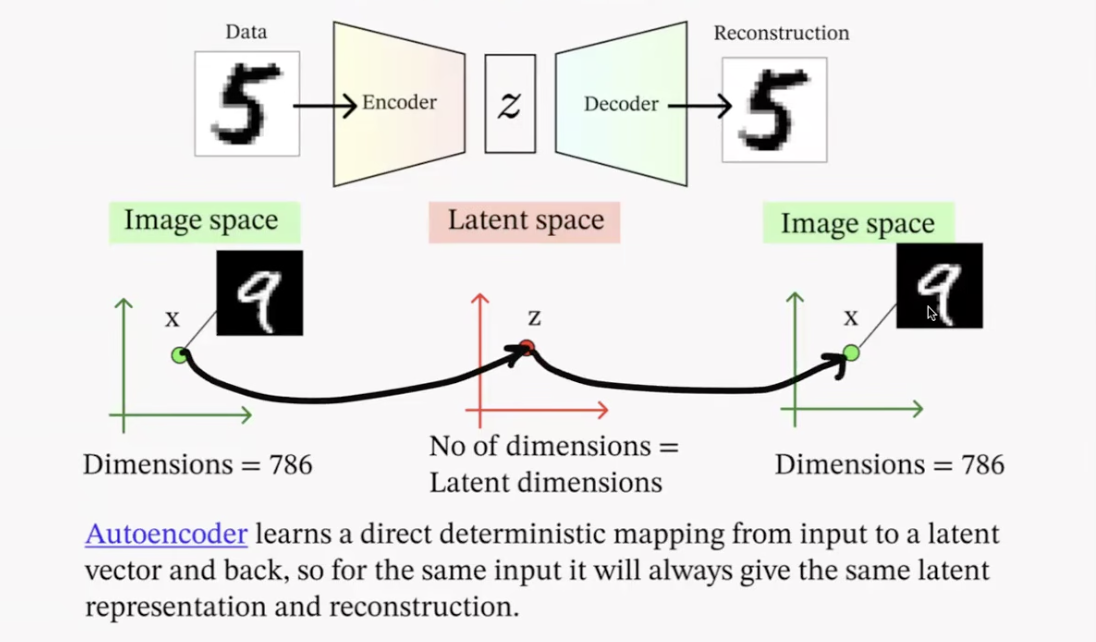
-
VAE
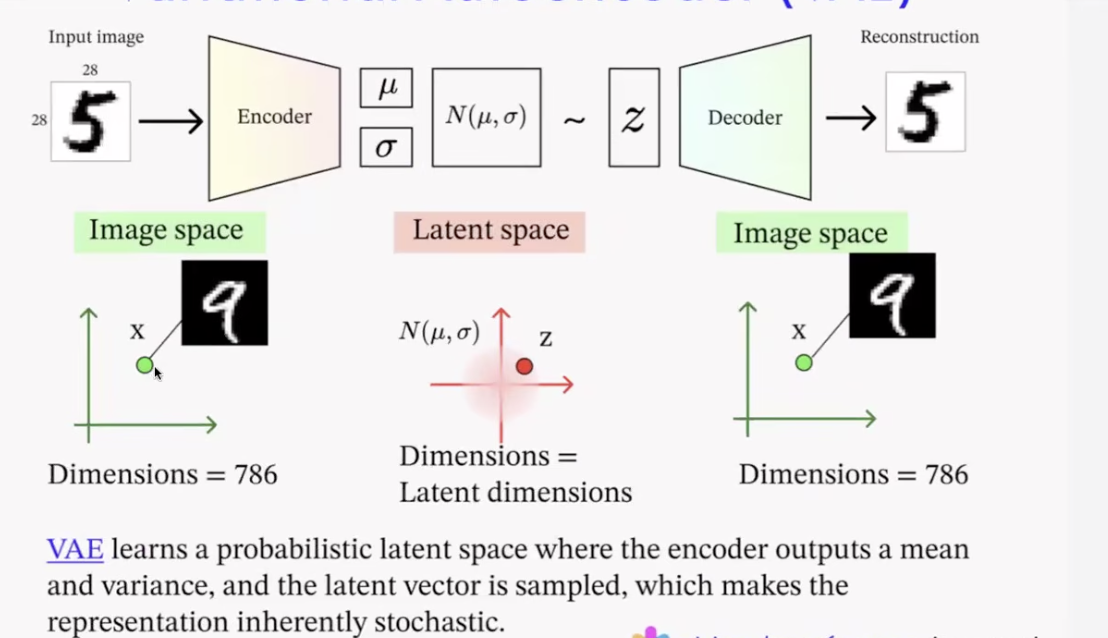
-
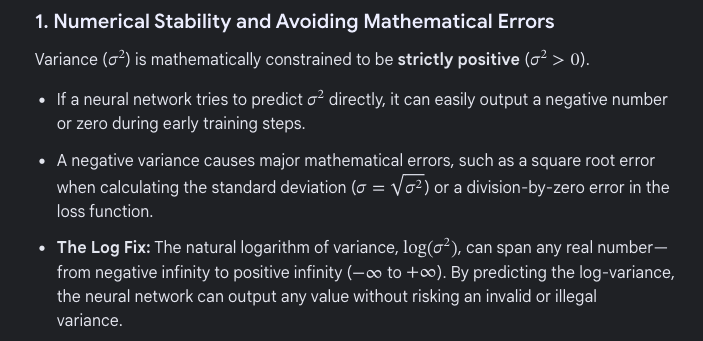
we are forcing the network to learn a dist with mu and sigma
-
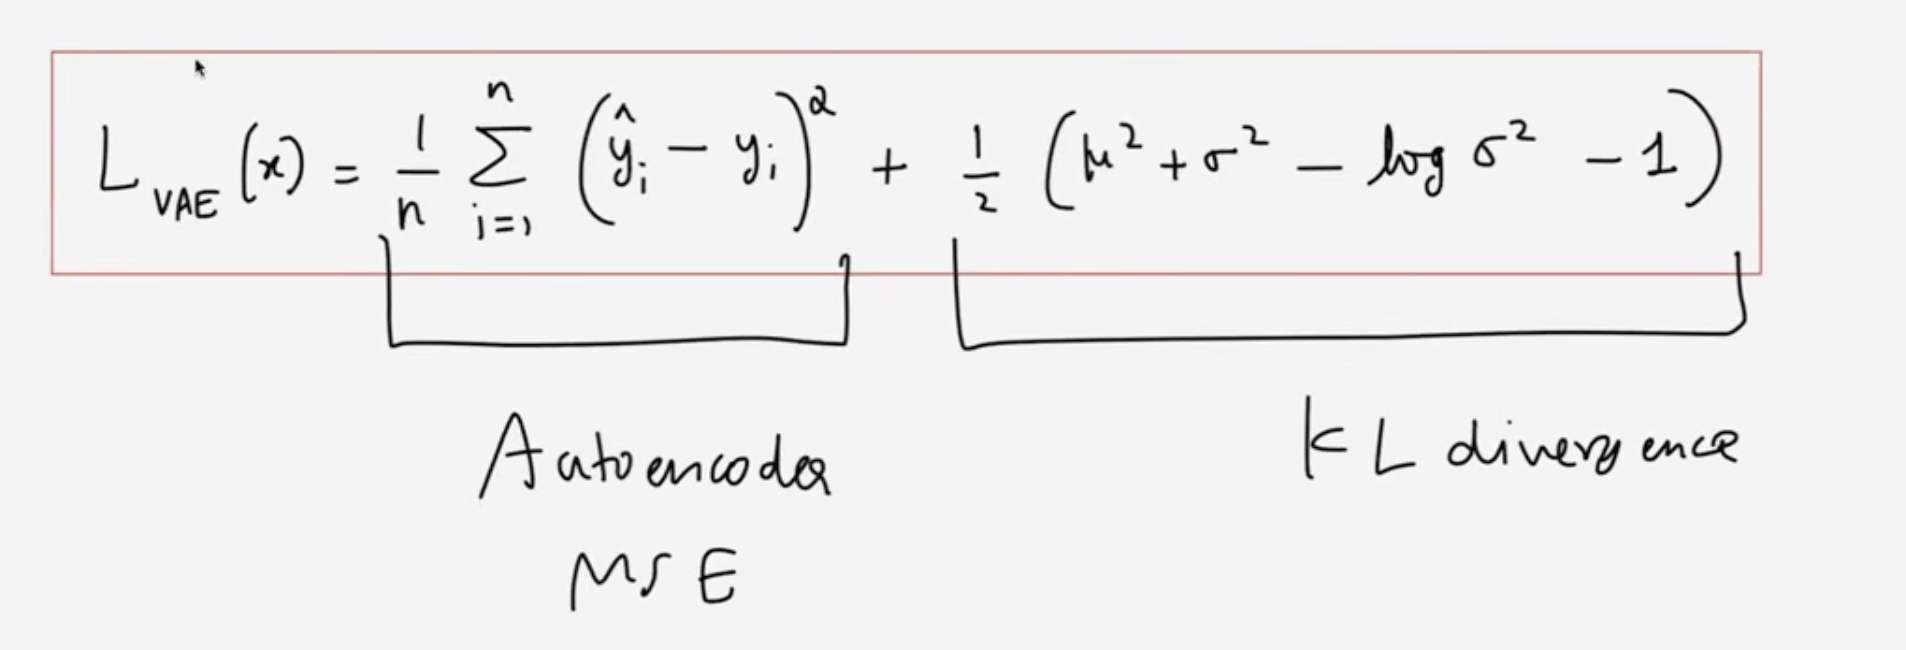
we are enforcing 2 things here:
- reconstructed image is similar to the original image
- penalize the model for predicting a dist farther from gaussian dist N(mu=0, sigma^2=1)
- something like - (mu-0)^2 + (sigma-1)^2 + (ŷi-yi)
- but instead we use the KL diverge to get the difference between the 2 dist instead of simply comparing the mean and the std dev with 0 and 1 as it results in a much smoother loss
implementation - https://colab.research.google.com/drive/1mqLfRsZPqdsOiEWSL0UwqpwMNYcC5lL0?usp=sharing
~aniket
Links:
202609212357